Personal project · 2026
Clarion
Speak in any language, get a clean English prompt for your coding agent, with a six-model evaluation behind its default.
- Desktop app
- Speech
- LLM evaluation
Overview
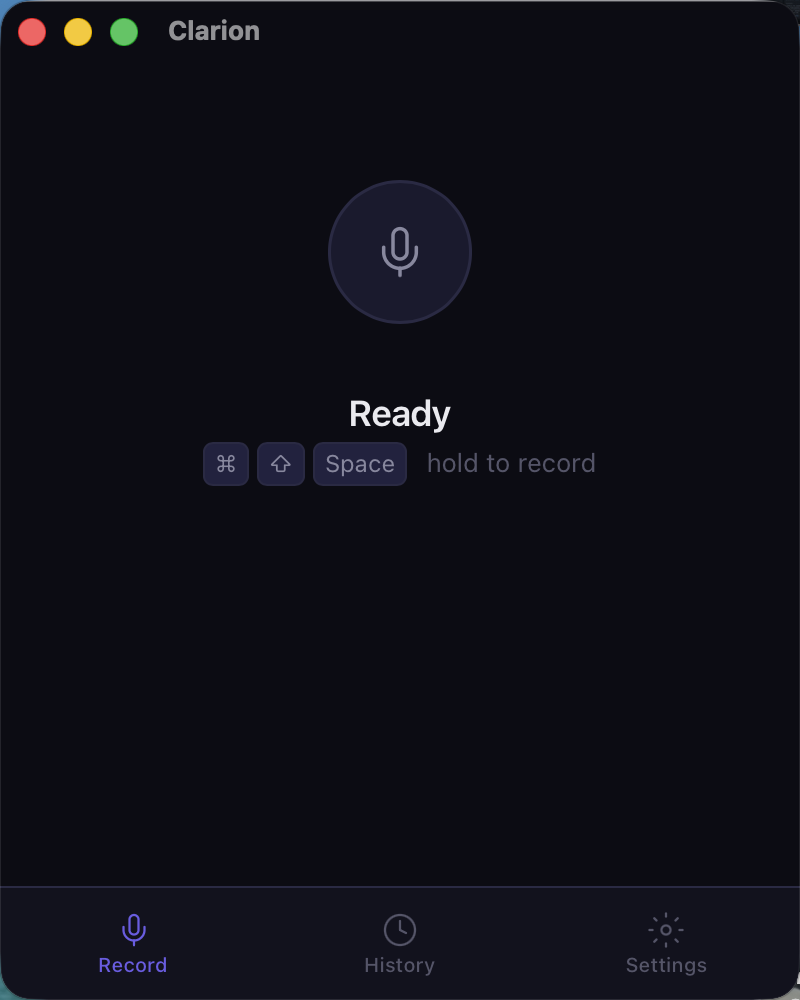
Hold a hotkey, speak in Persian, Arabic, Chinese, Russian, Spanish or French mixed with English technical terms, and release: Clarion transcribes the speech, rewrites it into a clean English prompt, and pastes it where you were typing. The hard part is that prose must be translated while code identifiers like useState must survive untouched. Which model does that best was measured, not guessed: an evaluation harness scores six models on 210 code-switched developer utterances, using the exact prompt and settings the app ships.
Contributions and results
- Tauri 2 app in Rust and Svelte (about 5 MB), with cloud Whisper or fully local whisper.cpp transcription and a pluggable structuring backend (Anthropic or Cohere).
- The harness pins the app's prompt by hash and fails CI if the two drift. Its primary metrics are deterministic (identifiers kept verbatim, no source-language text left, clean format, latency) and recompute exactly from the committed run files.
- On Persian, the one language reviewed by a native speaker, every model kept the output format clean, and the shipping default kept 98.6% of identifiers verbatim with no Persian left in the output.
- Median latency: about 1 s for the shipping default and the 3.35B Tiny Aya models, 3.4 s for Command A Translate, 8.5 s for Command A+.
- A controlled test of Cohere's regional tuning (same 3.35B model, only the tuning region varied) found no clear advantage: on Persian the three variants tied exactly. Provisionally, pending native review of the other five languages, the region-matched variant led on none of them.
- LLM judging is blind and uses one judge per vendor. The judges disagreed by 0.61 points on a 1–5 scale, so their scores are reported as weak evidence rather than used for the conclusions.
Results
| Model | Identifiers kept | Fully English | Format clean |
|---|---|---|---|
| Claude Haiku 4.5 (default) | 98.6% | 100% | 100% |
| Command A+ | 100% | 97.1% | 100% |
| Command A Translate | 95.7% | 100% | 100% |
| Tiny Aya Earth (3.35B) | 88.6% | 100% | 100% |
| Tiny Aya Water (3.35B) | 88.6% | 100% | 100% |
| Tiny Aya Global (3.35B) | 88.6% | 97.1% | 100% |
The other five languages are LLM-drafted and marked provisional until a native speaker reviews them.